

What is Sesame CSM? It's the Conversational Speech Model from Sesame, a text-to-speech model that can take the earlier turns of a conversation (text plus audio) as context, so the next line sounds like it belongs in that conversation. The smallest version, CSM-1B, is free to download from Hugging Face under the Apache 2.0 license, with code on Sesame's GitHub. To run it you need a CUDA graphics card, Python, and an approved Hugging Face login. It speaks English, it ships with no ready-made voices, and it can't think or write: it only turns text into speech.
If you came here because of the Maya voice demo, that's related but not the same thing. The demo used a fine-tuned version of CSM, and the company's main product today is an app. More on that below.
I'm Miguel Ángel, and I wrote this with help from an LLM to verify facts. I checked everything here on October 4, 2026, by reading Sesame's GitHub README, the model page on Hugging Face and Sesame's own site and journal. The setup steps below are the official ones from the README.
What CSM actually is
Most text-to-speech tools read each sentence as if nothing came before it. CSM is built to listen to the conversation first. According to the README, it generates audio codes from text and audio inputs, using a Llama backbone and a smaller audio decoder that outputs codes for Mimi, an audio codec made by Kyutai. Hugging Face's own docs describe it as the first open-source contextual text-to-speech model released by Sesame.
Sesame trained three sizes for its research: Tiny (1B backbone), Small (3B) and Medium (8B), on about one million hours of mostly English audio. Only the Tiny one, CSM-1B, was released, on March 13, 2025. Since May 2025 it also runs natively inside Hugging Face's Transformers library, so you don't strictly need Sesame's own scripts.
It's a voice, not a chatbot (Important)
The README's FAQ is blunt about it: CSM is an audio generation model and cannot generate text. If you want something you can talk to, you pair it with a separate language model, such as ChatGPT or an open model, that writes the replies, and let CSM speak them.
Where to download it (the real places)
There are only two official homes, and they're both free:
- GitHub, SesameAILabs/csm: the code, the setup steps and a quickstart script that generates a short conversation between two speakers.
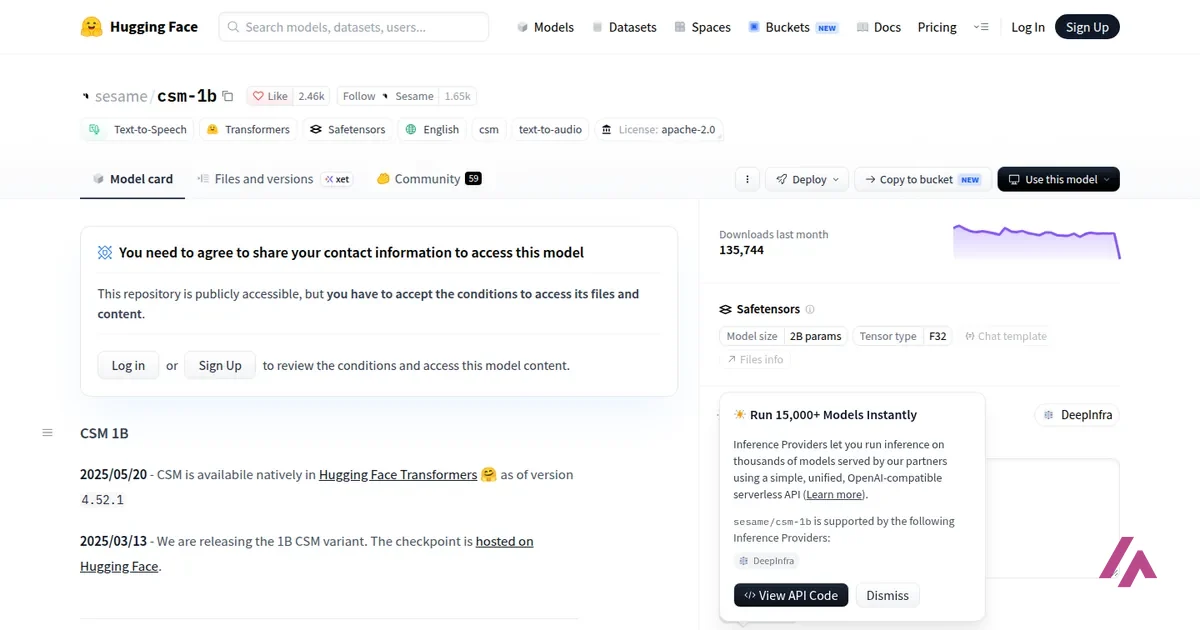
- Hugging Face, sesame/csm-1b: the model weights. It's tagged English, Text-to-Speech and apache-2.0, and it's gated: you need a free account and you have to accept Sesame's conditions, which include sharing your contact information.
There's also a Hugging Face Space from Sesame where you can type text and hear it, which is the quickest way to judge the voice before installing anything. Anything else is a third-party version, not Sesame's.
The Apache 2.0 license allows commercial use, although the README presents the release as being for research and educational purposes. Your obligations come from the license itself and from Sesame's own rules on misuse, which I cover further down.
What you need to run CSM-1B
The README lists the requirements. Here's the short version (it gets a little technical):
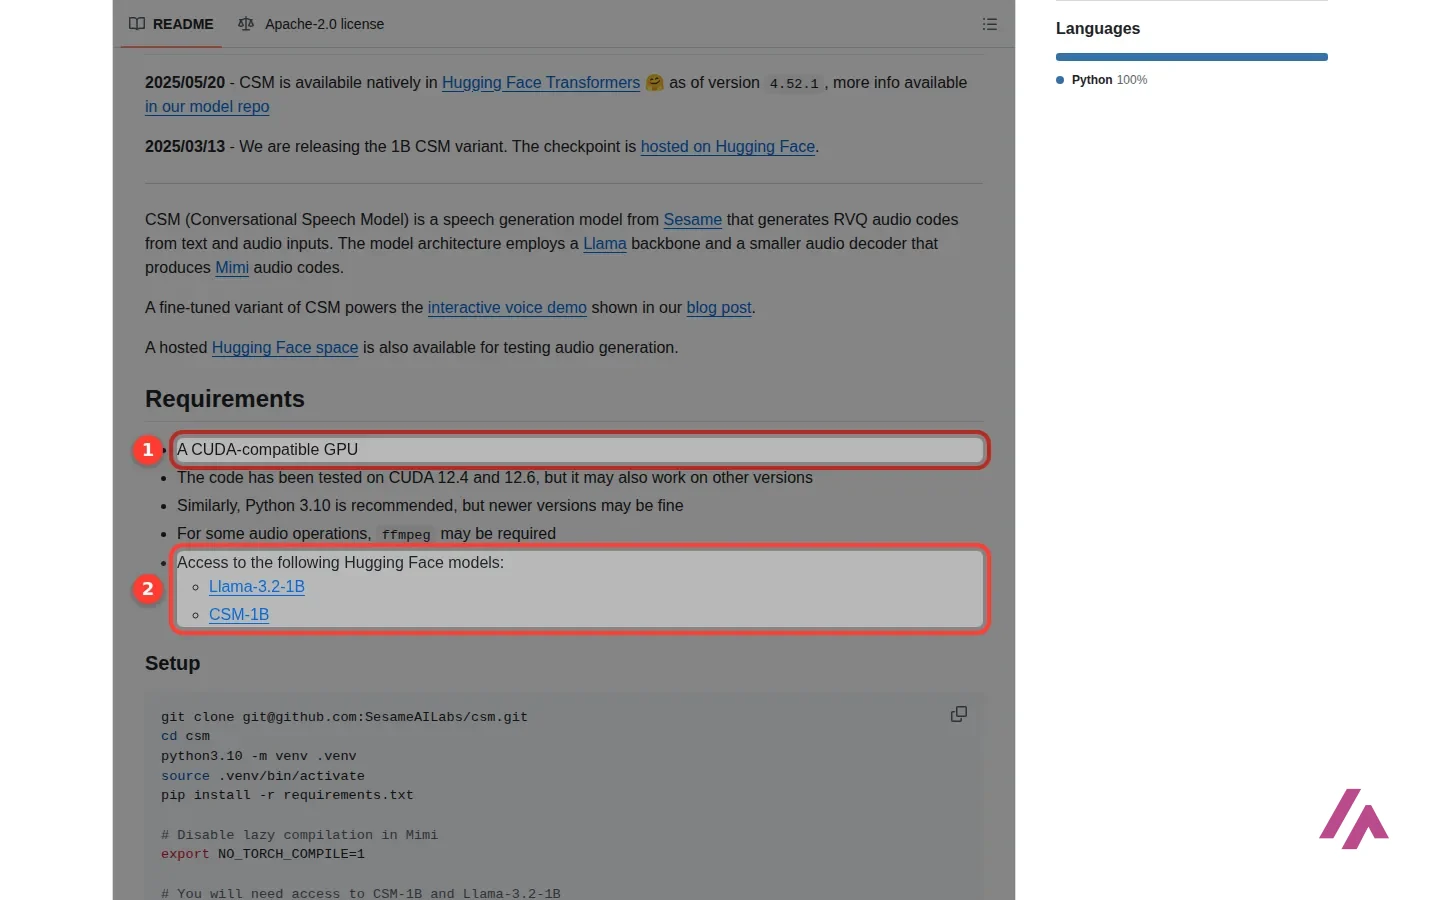
- A CUDA-compatible graphics card, which in practice means Nvidia.
- Python 3.10 is recommended (newer versions "may be fine").
- ffmpeg for some audio operations.
- Access to two gated models on Hugging Face: CSM-1B itself and Meta's Llama-3.2-1B, which Sesame's code also loads. Request both before you start, or the setup stops at the download.
On Windows there's one extra step: the triton package doesn't install there, and the README tells you to use triton-windows instead.
-
Get access on Hugging Face
Create a free Hugging Face account, open the CSM-1B and Llama-3.2-1B model pages and accept the conditions on each.
-
Clone the repo and install
Clone SesameAILabs/csm, create a Python 3.10 virtual environment and install the requirements file. The README also sets
NO_TORCH_COMPILE=1to disable lazy compilation in Mimi. -
Log in from the terminal
Run
huggingface-cli loginso the scripts can download the gated models. -
Run the quickstart
python run_csm.pygenerates a conversation between two characters, each with its own prompt. From there, the README shows how to generate a single sentence or a line with context.
If you already use Transformers, you can skip the repo: load sesame/csm-1b with CsmForConditionalGeneration, as Hugging Face's docs show, and you still need the approved login.
An independent install-and-test video posted the day after CSM-1B came out. According to its description and chapters, he installs it on a laptop with an RTX 4060 and 8 GB of video memory, checks how much of that memory it uses, explains how voice cloning works with it and clones his own voice. It's from March 2025, so check the setup steps against today's README.
What it does well, and what it doesn't
The key word is context. With no context, CSM uses a random speaker identity, because this is a base model that hasn't been fine-tuned on any specific voice. Give it a few earlier lines of the conversation, each with its text and its audio, and it uses them to shape how the next line sounds. The README puts it simply: "CSM sounds best when provided with context."
That same mechanism is how CSM can follow a voice: feed it real recordings of a voice as context and the next line follows it. That's why the model is so interesting, and why it comes with rules.
Now the limits:
- English first. The FAQ says it has some capacity for other languages due to "data contamination" in the training data, and that it "likely won't do well". Back in February 2025, Sesame's research post said it intended to expand to over 20 languages; for now, plan on English.
- No voices included. You bring your own reference audio or accept a random voice.
- No brains. It doesn't understand or answer you. That's the job of the language model you put in front of it.
- Hardware. No CUDA card, no smooth ride. The sample code can fall back to other devices, but the README's requirements and testing are all about CUDA.
The rules on cloning voices (Heads-up)
Sesame's README explicitly prohibits using CSM to mimic real people without their explicit consent, to create deceptive content such as fake news or fraudulent calls, and for anything illegal or harmful. Using your own voice is within those rules. Cloning someone else's needs their permission, and that applies to your aunt as much as to a celebrity.
The Maya demo, and what Sesame is today
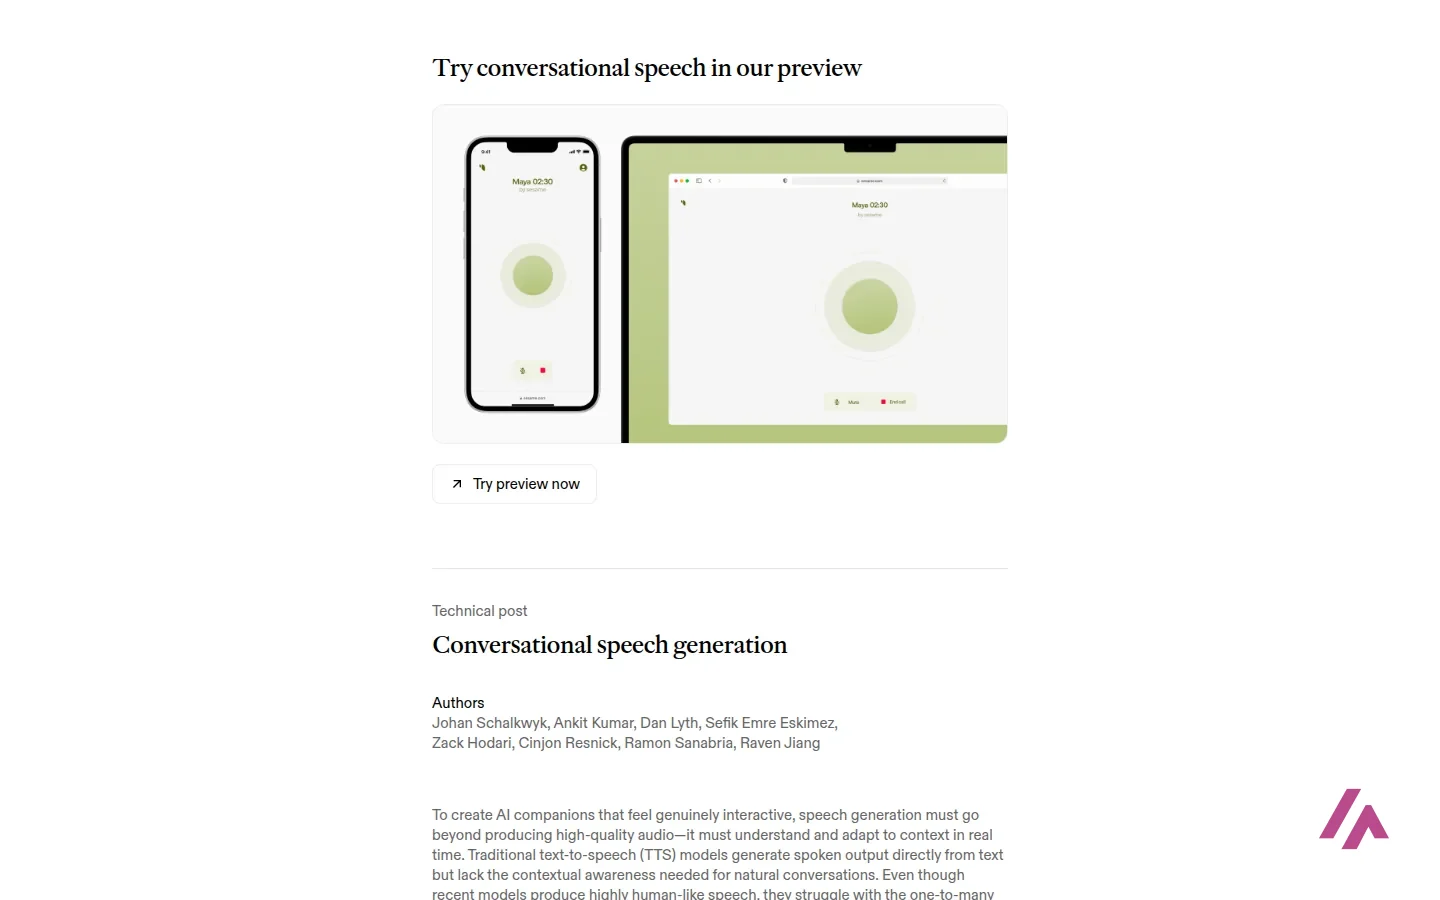
Sesame first made noise in February 2025 with a research post called "Crossing the uncanny valley of conversational voice" and a live voice demo (the preview shown in that post opens a call with Maya). According to the README, a fine-tuned version of CSM powers that demo. The open CSM-1B is the base model, so don't expect it to sound like Maya out of the box.
I opened that research post today, and the demo section now reads "Try conversational speech in our preview", with a "Try preview now" button that takes you to Sesame's web preview.
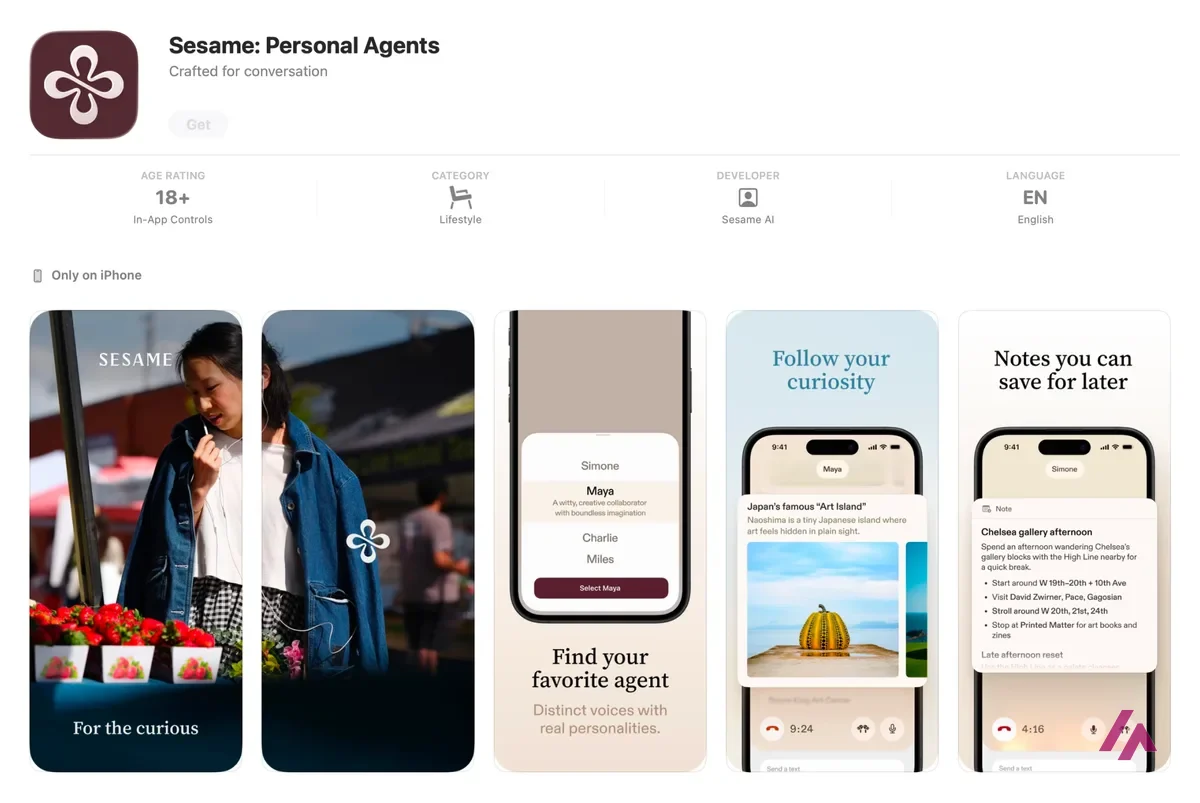
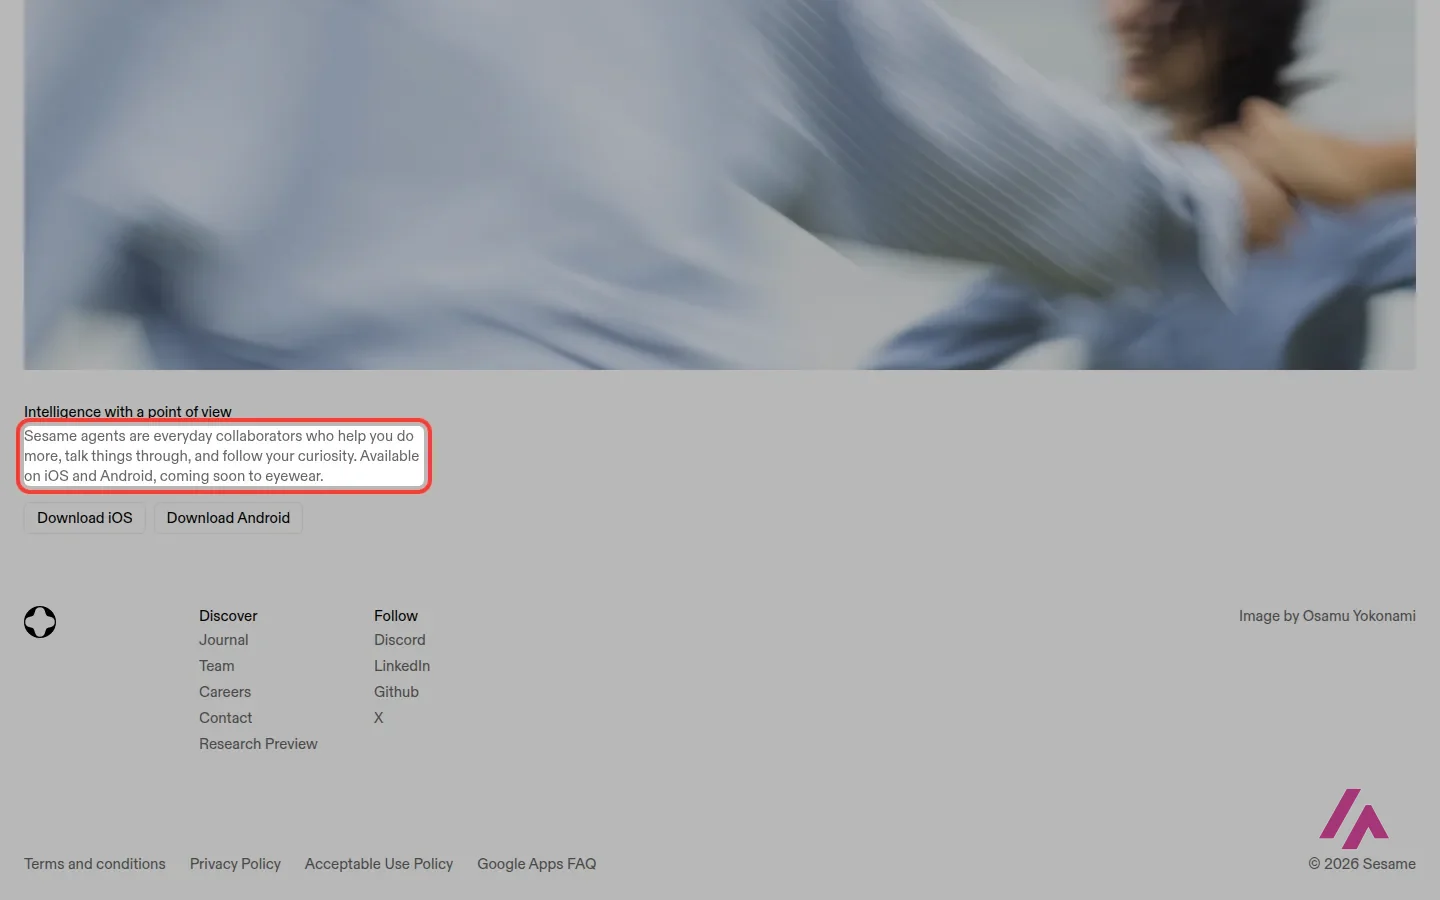
The company's focus is now its app. Its home page describes "Sesame agents" as everyday collaborators, "Available on iOS and Android, coming soon to eyewear". The iOS app, Sesame: Personal Agents, came out in May 2026 as a preview. Sesame's announcement said it was available in 39 countries, that the full experience was free during that first phase, and that you might hit a short waitlist. You pick from four voices, Maya, Miles, Simone or Charlie. The App Store listing says they can search the web, take notes, set reminders and summarize takeaways, with memory across voice and text, an Incognito mode and no ads. The same listing says intelligent eyewear is coming in 2027, so that one's still a promise.
On the business side, Sesame's team page names Brendan Iribe, Ankit Kumar, Ryan Brown, Angela Gayles and Nate Mitchell as its leaders and lists a16z, Sequoia, Spark and Matrix among its backers. The research team is still publishing, too: in August 2026 it released TurnBench, an open benchmark that measures the timing of turn-taking in spoken conversation.
A short CNBC report by Deirdre Bosa from early March 2025, days after Sesame's voice demo came out. It's a news piece from that moment, before Sesame's app existed.
Who should bother with CSM-1B
If you're a developer building a voice agent, a game character or an audiobook pipeline in English, and you have an Nvidia card, CSM-1B is one of the few open models designed around conversation rather than single sentences. The Apache 2.0 license makes it usable in a product (the README frames the release as research and education), and the context trick is genuinely useful for keeping a voice consistent from line to line.
If you just want to use Sesame's voice agents, you don't need any of this: the app or the web preview is the product, and the model is the engine behind it. And if you need Spanish, French or any other language, CSM-1B isn't your model yet. My advice: try Sesame's Space on Hugging Face first. Five minutes of typing will tell you more about whether it's worth an afternoon of setup than any README.
In IT since 2002: systems, engineering, web development and SEO. I have been doing business with AI since February 2023, when ChatGPT could first be bought in Spain.

Anything left unclear? Ask me
I’m Miguel Ángel, and I’ll answer you myself, right here. And if something is out of date, tell me and I’ll fix it.