
Imagine a vast ocean of knowledge where words are not just fragments of information, but authentic living beings capable of understanding and generating human text. This is the magical universe of Large Language Models (LLMs), which have taken natural language processing to unimaginable levels. If you are a software developer, get ready to embark on a fascinating journey through the inner workings of these linguistic mechanisms. Names like GPT-4, Claude, and Llama have revolutionized the landscape of artificial intelligence in recent years, and here we tell you how it all works. Ready for takeoff?
Fundamentals of Large Language Models (LLMs)
An LLM is a form of artificial intelligence designed to process and generate human language. It uses deep neural networks to learn patterns and relationships within large volumes of linguistic data. And what does “large” mean? Well, it refers to the immense amount of data with which it is trained and the millions of parameters that the model adjusts to make its predictions.
The magic of these models lies in their foundation: the Transformer architecture, introduced in 2017 in the famous paper “Attention Is All You Need.” Unlike recurrent neural networks (RNNs) or convolutional networks (CNNs), the Transformer uses self-attention mechanisms to capture the contextual relationships between all the words in a text simultaneously.
Does it seem complicated? Don’t worry, let’s break it down. An LLM consists of several neural layers: from dozens to hundreds of identical transformer layers, each processing features hierarchically. For example, GPT-3 has 96 layers, while LLaMA has up to 70.
But what about tokens? A tokenizer is responsible for transforming text into discrete units. For example, the phrase “AI is fascinating!” could be converted into tokens like [“AI”, “is”, “fas”, “cin”, “ating”, “!”]. If you haven’t caught anything… our friend Carlos Santana explains it better:
Embeddings: The Pillars of LLMs
Embeddings are fundamental for an LLM to represent tokens (words, subwords, or characters) as numerical vectors. Each token is transformed into a high-dimensional vector (for example, 768 or 4096 dimensions). During training, the model learns these vectors, capturing the semantic meaning of each token. It is interesting to note that developers do not set these dimensions; the model does it automatically during its training. For example, similar concepts like “cat” and “feline” will be close in the vector space, while others, like “galaxy” and “ice cream,” will be far apart.
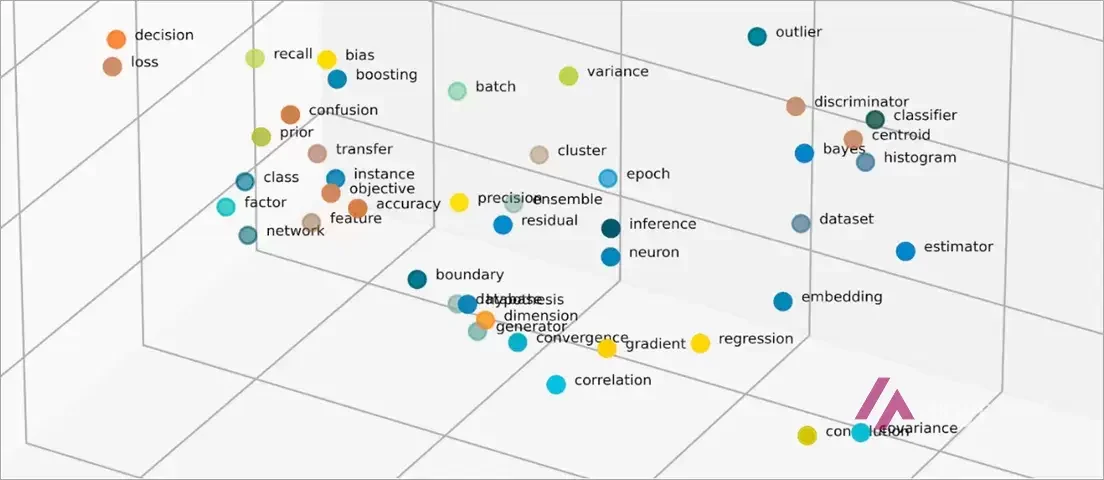
Positional Encodings and Embeddings
Positional encodings are crucial for LLMs to maintain the order of tokens in the input. When a text is broken down into tokens, the sequence that is essential for understanding the context is lost. This is where positional encodings come in, which are added to the embedded tokens to remember their order. These encodings are learned during training and allow the model to understand the relationships between the tokens and their position.
Feed-Forward Layers: The Diligent Workers
Feed-forward layers are the true workhorses of LLMs. They process the embeddings and generate a continuous representation of the input text. Their function is vital for the model’s performance, and each layer contributes to the complexity of the processed information.
Self-Attention and Multi-Head: Understanding Context
Let’s think of a sentence like: “The dog chased the clever cat all around the house. It managed to hide in time.” Each word in the sentence is interconnected. The word “dog” relates to “chased” and “cat.” LLMs use self-attention to calculate how much attention each token should pay to the others. But since there can be many relationships, this is where the concept of multi-head comes in, where multiple aspects of the relationship are analyzed at the same time.
The challenge lies in not losing important connections between sentences. If an LLM only processes sentences in isolation, it may forget that “it” in the second sentence refers to the “cat” in the first. This is where cross-attention plays its role, allowing the model to consider broader relationships in context.
In the next installment, we will delve into hardware requirements and the different pre-trained models. So stay tuned… you can already go get some ibuprofen and a bit of water.
In IT since 2002: systems, engineering, web development and SEO. I have been doing business with AI since February 2023, when ChatGPT could first be bought in Spain.

Anything left unclear? Ask me
I’m Miguel Ángel, and I’ll answer you myself, right here. And if something is out of date, tell me and I’ll fix it.